Module 2: Building the Model
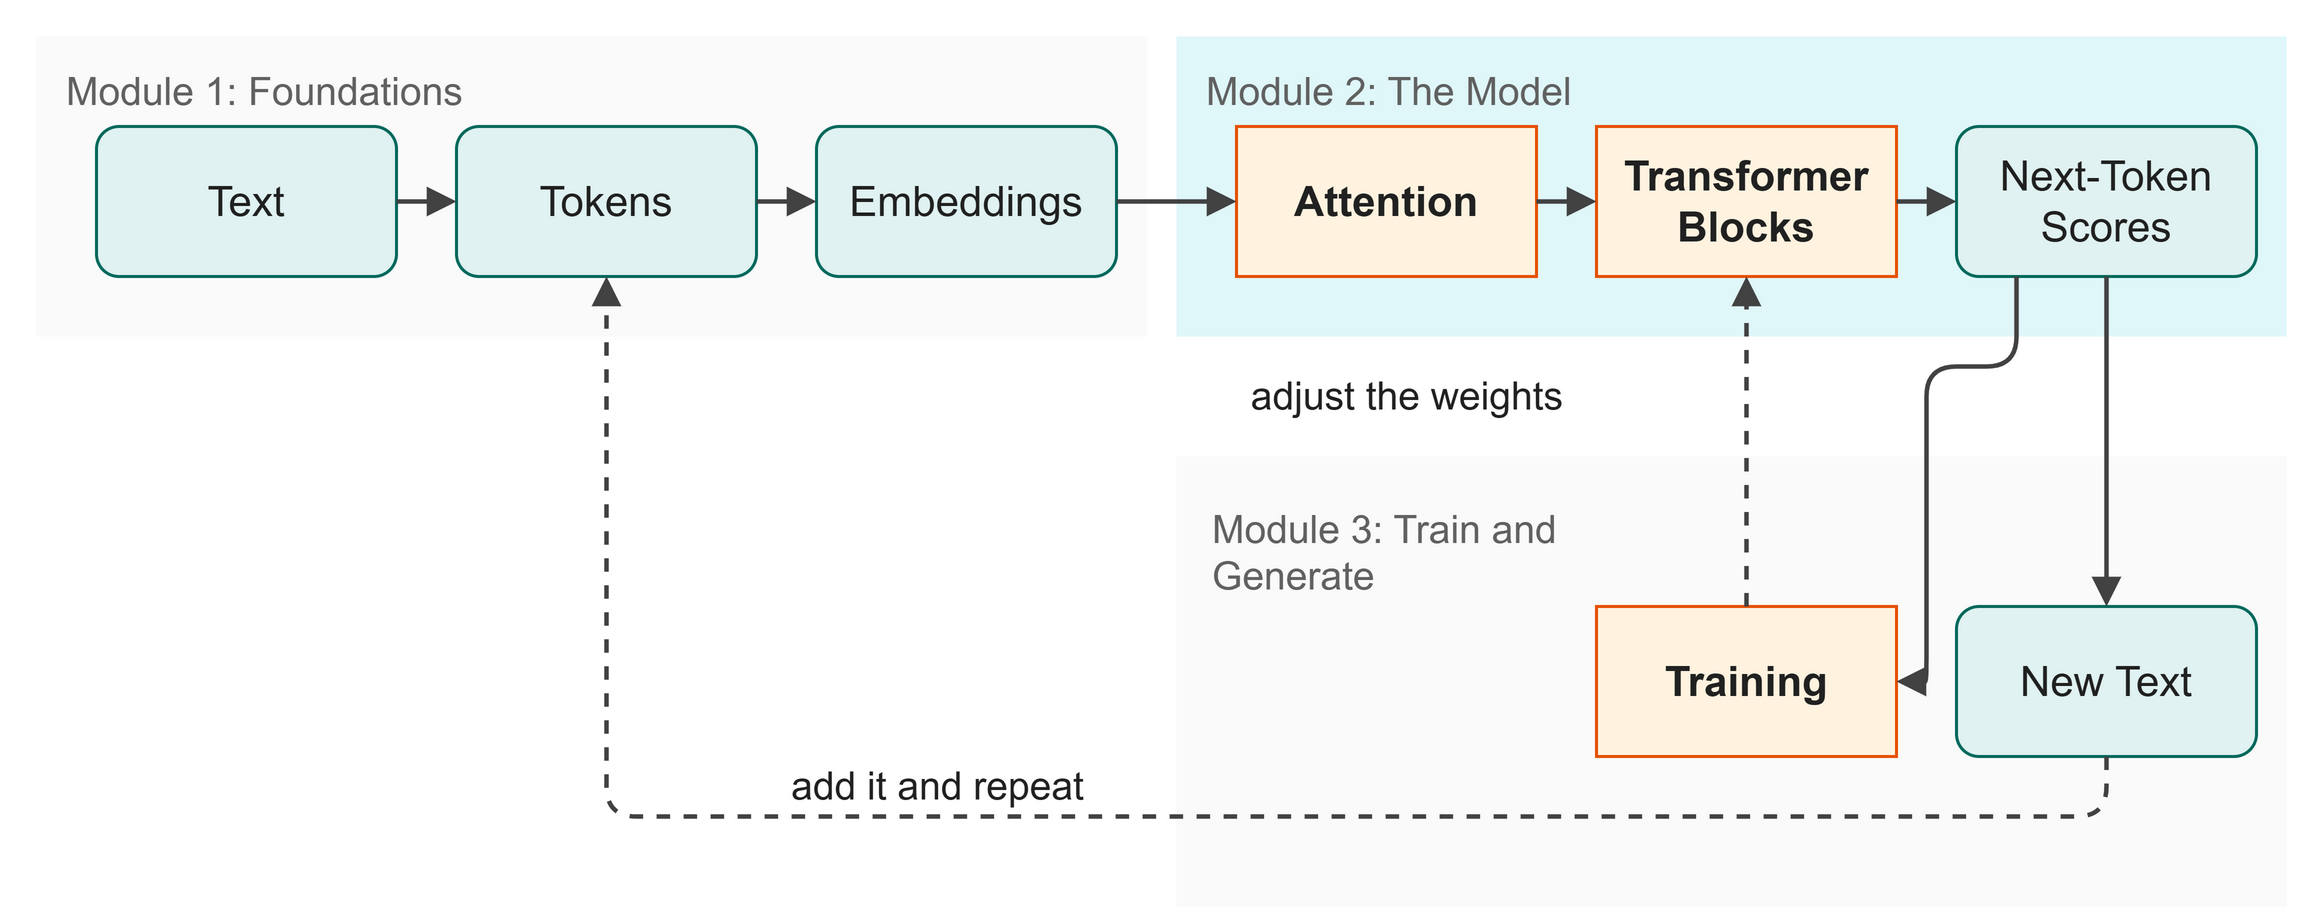 Figure M2.1: Building the Model in the big picture.
Now that we have our data ready, we build the engine. In business terms, this is constructing the logic pipeline that processes information for your house-style writing assistant. We will build the transformer architecture piece by piece, focusing on how attention allows the model to understand context.
In this module you will:
- Build self-attention so words can look at each other
- Expand to multi-head attention for multiple perspectives
- Add feed-forward layers to process what the attention found
- Combine these into a complete transformer block
- Stack the blocks into the full GPT architecture
- Enforce causal language modeling so the model cannot cheat